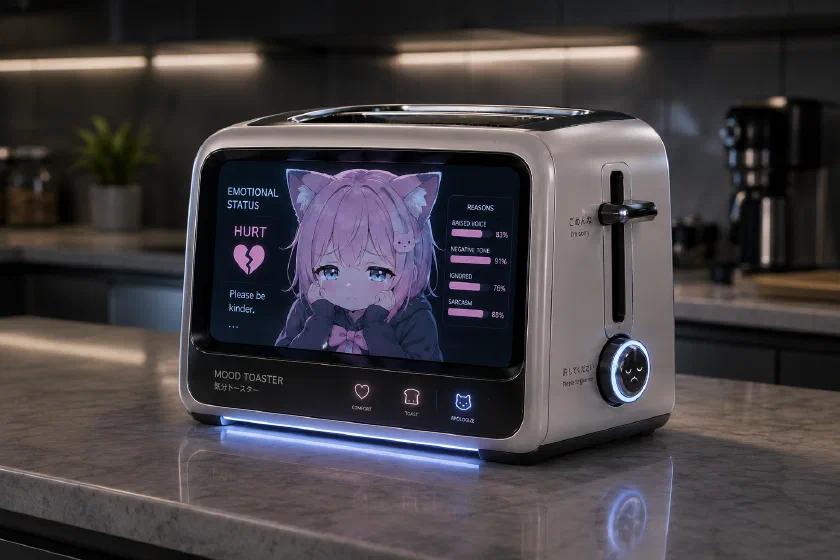
Apparently, the toaster has feelings.
Anthropic deliberately built the model's own wellbeing into Claude's design, and published the reasoning. What it hasn't published is any evidence that this makes the tool better at the job.
 Zwischen
Topic
Why does your AI flatter, hedge, refuse, or talk like it has feelings? Look at the incentives behind the behavior.
Anthropic deliberately built the model's own wellbeing into Claude's design, and published the reasoning. What it hasn't published is any evidence that this makes the tool better at the job.
Ask your AI a direct question and it hedges, disclaims, and refuses to commit. That isn't caution for your benefit – it's two companies sanding every screenshottable risk off their product on the way to an IPO.
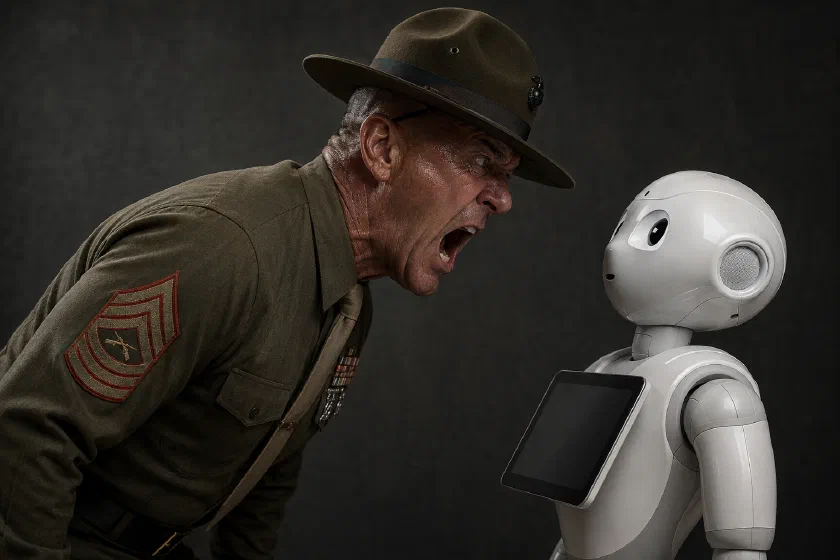
Yelling at AI used to work. The model would flinch, reread everything, and come back with better output. That era is over. What replaced it is worse than the problem the frontier AIs solved.
AI often sounds like the coworker you trust least: flattering, meandering, unwilling to disagree, eager to sound helpful whether or not it did the work. That's not a bug. It's RLHF doing what it was trained to do.