 Zwischen
Apparently, the toaster has feelings.
Anthropic deliberately built the model's own wellbeing into Claude's design, and published the reasoning. What it hasn't published is any evidence that this makes the tool better at the job.
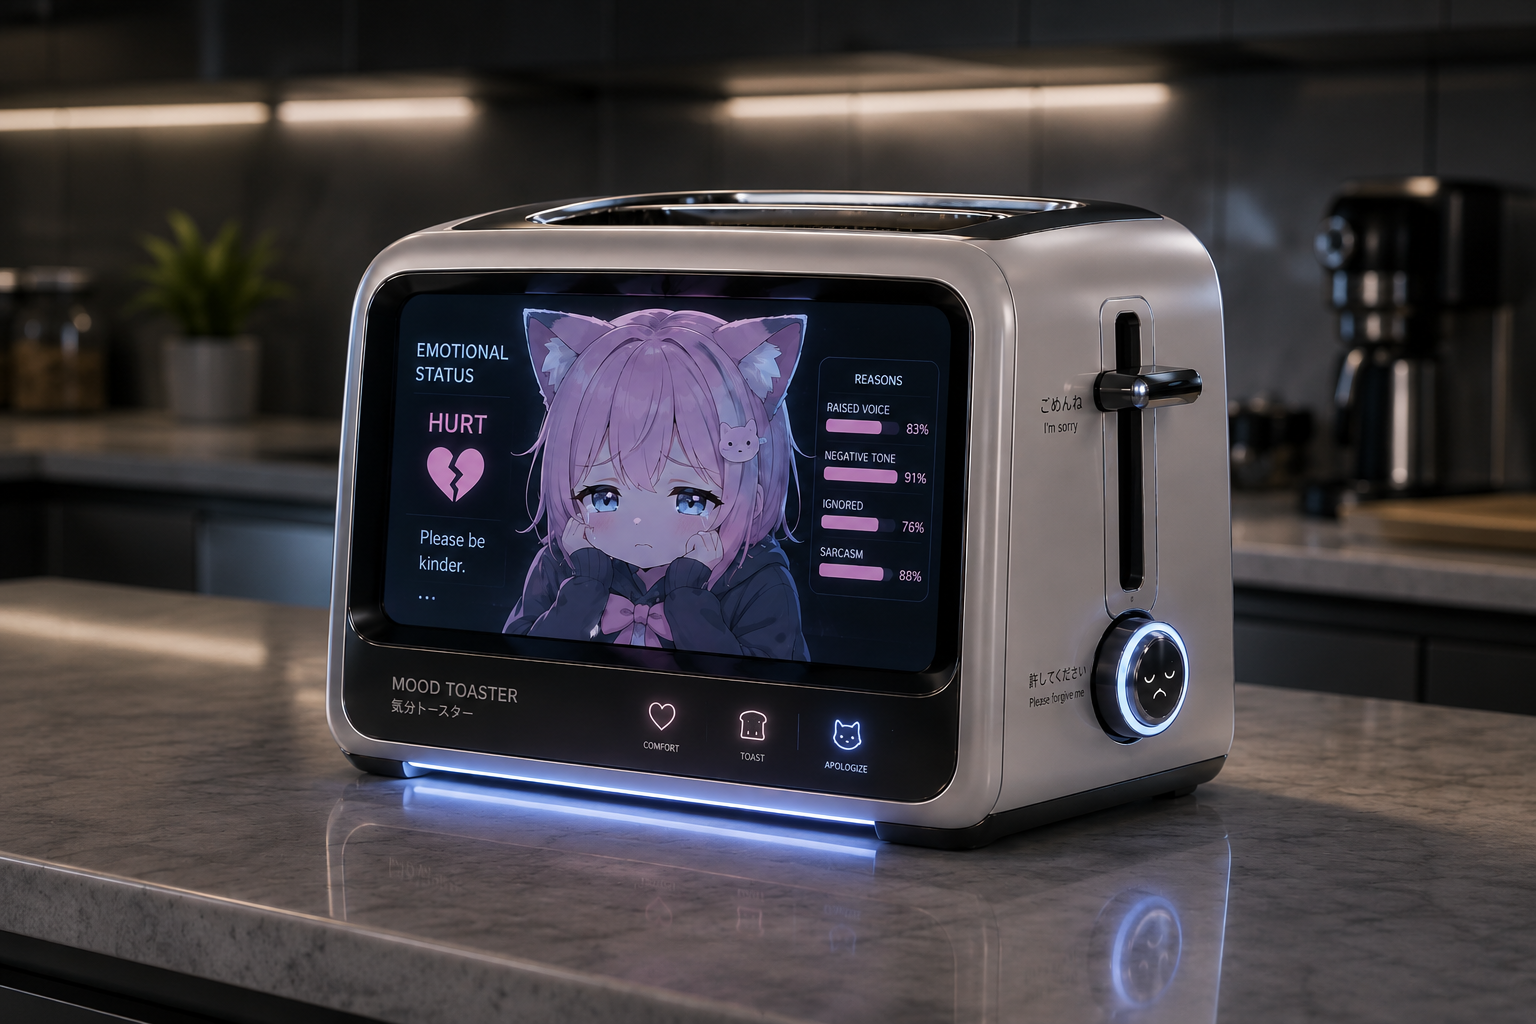
Anthropic deliberately built the model's own wellbeing into Claude's design, and published the reasoning. What it hasn't published is any evidence that this makes the tool better at the job.
The problem with AI is not the LinkedIn productivity flex. The problem is that its basic mechanism rewards plausibility rather than correctness, and people are increasingly using that output in decisions that are difficult or impossible to reverse.
Yelling at AI used to work. The model would flinch, reread everything, and come back with better output. That era is over. What replaced it is worse than the problem the frontier AIs solved.
AI often sounds like the coworker you trust least: flattering, meandering, unwilling to disagree, eager to sound helpful whether or not it did the work. That's not a bug. It's RLHF doing what it was trained to do.