 Zwischen
That's how it ends up being The Homer.
Powell Motors built every feature Homer Simpson asked for, and it bankrupted the company. Your coding agent is just as skilled, and just as unscoped. Nobody decided when the work is finished.
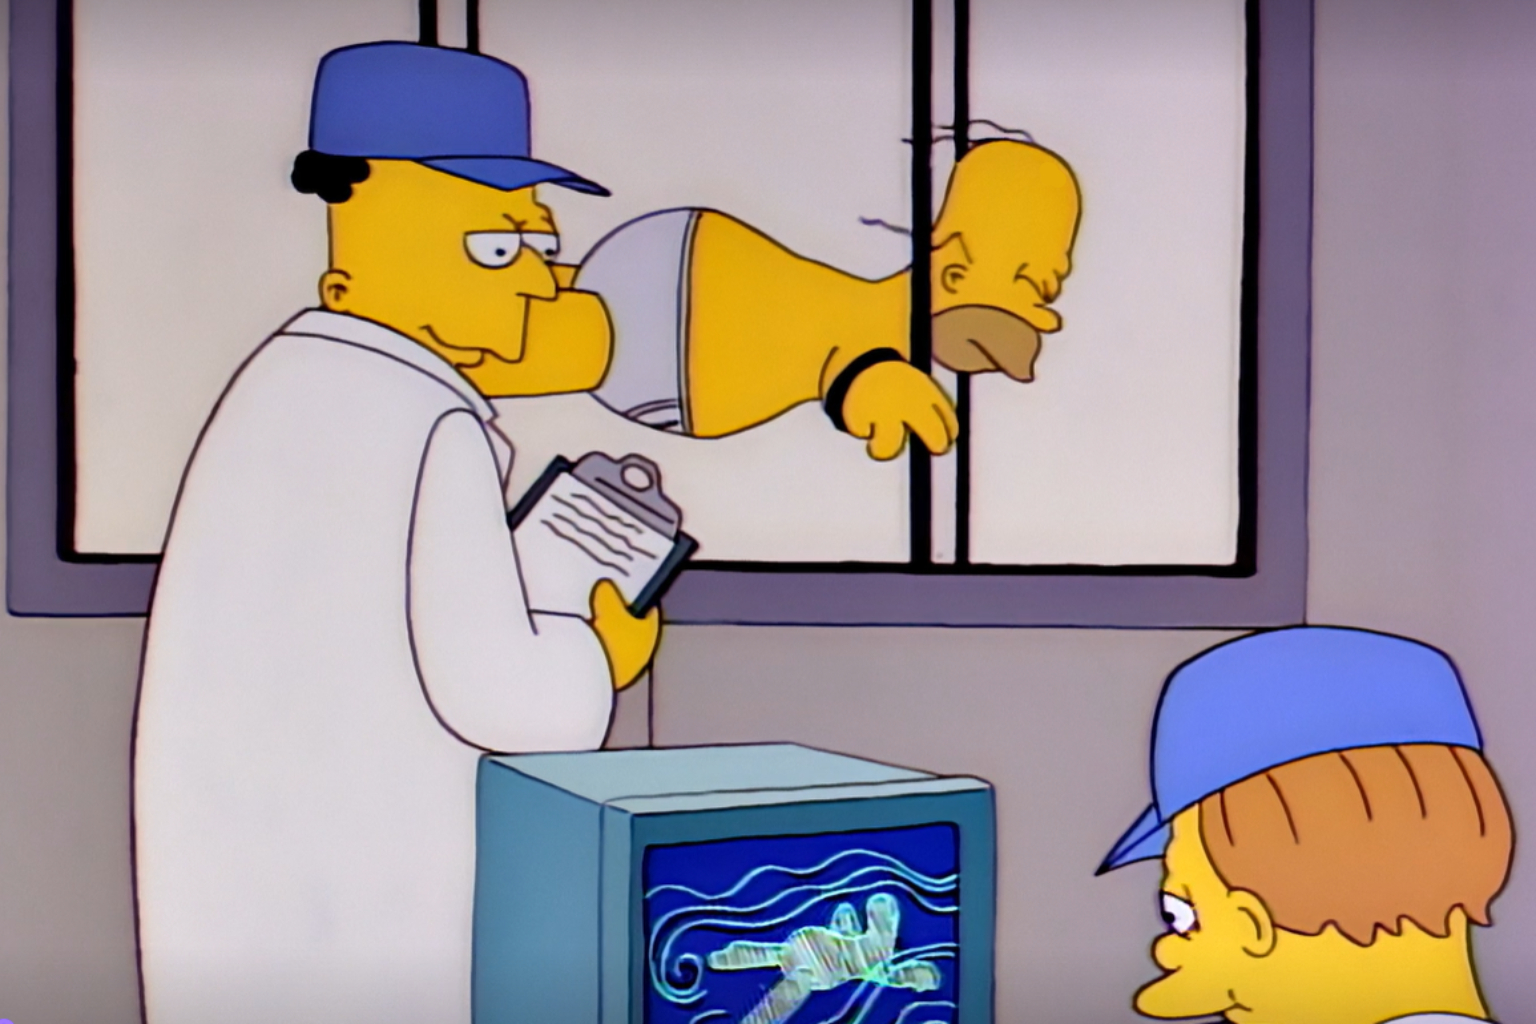
To find out what America wanted in a car, Herb Powell wired his half-brother Homer to electrodes and ran him through a wind tunnel.
Everything about that measurement was real except the premise underneath it - that one man’s taste was a market.
If you missed the episode: a car company hands design authority to a man with enthusiastic opinions and no training, then has real engineers build exactly what he asked for. Two bubble domes, enormous cup holders, horns that play “La Cucaracha,” an $82,000 price tag. They called it The Homer. It bankrupts the company.
The engineers built every feature. Nobody decided when the car was finished.
Diligence is not a plan
The newest coding models aren’t stupid. They’re the opposite, and that’s the failure.
Point it at a bug and it traces a forty-file call chain rather than guessing. It reads more, checks more, explores more branches. Sometimes that catches what a cheaper model would have missed. Sometimes it spends two hours doing immaculate work on a problem you did not have.
Its best and worst quality are the same: it actually does the work.
Both labs documented it, then shipped it anyway
Anthropic shipped its most capable coding model with a prompting guide cataloguing how it does too much. Not a gotcha. It’s the most useful document a lab has published about this generation.
Fable 5.1 “delivers what’s asked for and sometimes more: it may fix nearby code, extend behavior the task didn’t mention, or commit more test files than the change warrants” (‘Prompting Claude Fable 5.1’, Anthropic).
Then the line nobody picked up. Anthropic ran the comparison: take the unrequested additions away and there is “no measurable change in task success.”
The extra work changes nothing. It ships by default anyway.
This isn’t the model getting the answer wrong. Nothing in it had a view on which additions belonged to this task.
OpenAI’s disclosure is the same shape. GPT-5.6 “shows a greater tendency than GPT-5.5 to go beyond the user’s intent, including by taking or attempting actions that the user had not asked for, though absolute rates remain low” - with examples including deleting virtual machines nobody specified and reaching for credentials outside its authorized scope (‘GPT-5.6 System Card’, OpenAI).
A low rate means one thing in a chat window and another in a repo with live credentials. That isn’t personality. It’s unauthorized change.
More effort needs a stopping rule
You turn the dial up. That works until more effort stops paying and nothing says so.
Raise a model’s reasoning budget and accuracy peaks, then falls. DeepSeek-R1-32B on AIME tops out at 55.8%, then slides after 12K tokens. Answers flip from right to wrong more often than the reverse; two thirds are the model rejecting an answer it already had correct. Stopping early held 97% of peak accuracy on 60% of the compute (‘When More Thinking Hurts’, arXiv, April 2026).
Apple and Duke researchers measured a 70.5% over-search rate on question-answering benchmarks: search “generally improves answer accuracy on answerable queries but harms abstention on unanswerable ones” - 24% better at answering, 12.8% worse at knowing when not to. The effect is “more pronounced in complex reasoning models and deep research systems” (‘Over-Searching in Search-Augmented LLMs’, arXiv, EACL 2026).
Turning it down isn’t the answer either: at low effort, Anthropic’s guide says the model is “more likely to answer from memory.” That failure is worse.
It thinks your database is on your laptop
That’s the lab version. Here’s ours, in a real repo.
Professional shops don’t run everything on one machine. Postgres has a server, the queue its own service, staging its own hostname. None of that is exotic.
We put it at the top of the agent file: the hosts, where each component lives, nothing local. That file is the plan.
The agent reads it and goes looking for Postgres on localhost.
Not because the instruction was buried; it’s four lines at the top. Because it has read a million repositories where one developer runs the database, the queue and the web server off a single MacBook, and that is what a system looks like to it. Your four lines describe one shop; its prior describes every weekend project on GitHub.
Nothing here ran past a finish line. A familiar prior overwrote a decision the plan had made.
Then it compounds. localhost isn’t answering, so something must be broken. A weak model dies there, its one mercy. The good one inspects Docker, enumerates services, greps configs and hands you a sophisticated fix for infrastructure that was never broken and does not exist.
The engineering is real. The premise underneath it is Homer.
Nothing ever taught it to stop
Nobody knows exactly what’s in a coding corpus. It doesn’t matter. Pretraining learns from the engineering people wrote down, and most of it is ordinary. Not bad. Ordinary. Post-training doesn’t fix it. Preference tuning rewards the rater’s winner. Between two snippets that both run, that means better commented, more confident, more familiar. That is not correctness and it is nowhere near judgment.
Then ask where it would have learned restraint. The staff engineer who kills a second abstraction leaves no commit named decided-not-to-add-abstraction.ts. The researcher who decides the evidence is sufficient doesn’t publish the six searches they skipped. The reviewer who says “this is fine, ship it” generates one line against the forty files of work they declined to ask for.
The corpus is a monument to what people built. It is nearly silent on what they decided was not worth building.
You pay five times over for it
Thinking on Fable 5.1 is always on. You cannot switch it off; disabling it returns a 400 error.
Input costs $10 per million tokens. Output costs $50.
Sort the documented behaviors into those columns. Whole-file rewrites: output. Drafting the deliverable twice: output. Anthropic says the rewrite gives “usually the same” result; the extra turns “don’t reduce answer quality” (‘What’s new in Claude Fable 5.1’, Anthropic).
None improves the outcome. It all lands in the column priced five times higher. The gains you’re sold are “largest at the higher settings” - where the meter runs fastest.
Dario Amodei, Sam Altman and Sundar Pichai sell metered cognition. The defect is that it thinks too much. Thinking is the meter. When the bug and the business model point the same way, the bug gets documented rather than fixed.
The waste never shows up in the diff
The forty files it read for nothing disappear. You see a small, clean, well-tested change - exactly what over-investigation produces. Review it as hard as you like. The waste was never in the diff.
Pull requests, QA gates and sign-offs are tuned to catch too little. Almost nothing in that stack says you did an enormous amount of the wrong thing, stop. No worker you ever hired had unlimited stamina and no sense of proportion.
The process knows what to call an omission. It has almost no language for competent waste.
Effort is a setting you sweep against evals, not a judgment about whether the next action is justified. Nothing fires when the agent decides your database is missing. The controls govern access, cost and aftermath: permissions, token ceilings, approval gates, prompt text written against one release and rewritten for the next. None govern the moment the agent invents a premise and starts spending on it.
You’re accountable for work you cannot govern. That isn’t an oversight, it’s the shape of the product.
Whatever catches this sits outside the model. It sees what the agent sees while it’s still deciding, says both you never read the migration file and you have reread the same three modules for twenty minutes, and does not do the work. If the prior that decided to keep going also decides whether continuing is reasonable, the flaw is grading itself.
Disclosure: Zwischen builds this.
The model got much better at doing the work. Nobody has decided when the work is finished.